Speech & audio AI · Original project
ForgeGuard Faster Whisper Server
Container-native, OpenAI-compatible speech-to-text built on faster-whisper and CTranslate2, with an operationally safe deployment story.
- Status
- Active
- License
- MIT
- Latest release
- v1.1.0
- Model
- whisper-large-v3
Overview
What it solves.
ForgeGuard Faster Whisper Server exposes OpenAI-style /v1/audio/transcriptions and /v1/audio/translations endpoints backed by Whisper large-v3 running on CTranslate2. It packages the operational details self-hosted transcription needs: baked-in model weights, warmup-aware health and readiness, optional bearer authentication, built-in HTTPS, upload limits, request queuing with load shedding, and live GPU telemetry.
Transcripts are treated as sensitive data by default: input text is never logged unless explicitly enabled, and uploaded audio is not persisted beyond the request.
Verified capabilities
What it does.
- OpenAI-compatible transcription and translation/v1/audio/transcriptions and /v1/audio/translations accept multipart uploads with json, text, and verbose_json responses; any OpenAI SDK works unchanged.
- Word-level timestampsverbose_json returns per-segment detail plus a words array with start/end times and probabilities when timestamp_granularities[]=word is requested.
- Voice-activity detectionVAD filtering (on by default) skips non-speech so silence is not transcribed.
- Runtime model pickerSwitch the resident Whisper model (tiny through large-v3, large-v3-turbo, distil-*) at runtime via the auth-guarded /api/model/activate; the choice persists across restarts.
- Warmup-aware health contractConnections are accepted immediately while the model warms in the background; /health, /ready, and Retry-After semantics keep probes accurate, and failed warmup exits non-zero.
- Optional bearer authentication and built-in HTTPSA single API_KEY gates API routes; TLS_ENABLED=true serves HTTPS directly with an auto-generated, persisted self-signed certificate by default.
- Bounded concurrency with load sheddingMAX_CONCURRENCY and QUEUE_SIZE bound in-flight work; excess requests shed with 503 instead of piling up, and /system reports the live queue.
- Privacy-first defaultsLOG_INPUT_TEXT defaults off because transcripts are PII; PERSIST_AUDIO defaults off so uploads never outlive the request.
Operational facts
The operating contract.
| API contract | OpenAI-style /v1 routes; interactive reference at /docs |
|---|---|
| Runtime | faster-whisper on CTranslate2; float16 on GPU with automatic int8 downgrade on CPU |
| Distribution | Container images (ghcr.io) + Helm chart; no supported bare-metal install |
| Authentication | Optional bearer token via API_KEY; /health, /ready, and the console stay open |
| Health / readiness | /health liveness and /ready readiness with warming semantics and Retry-After; failed warmup exits non-zero |
| Observability | /system reports GPU utilization, VRAM, temperature, power (NVML best-effort) plus in-flight and queued requests |
| Persistence | TLS material and active-model choice under DATA_DIR; uploads not persisted; weights baked into images |
| Supported hardware | NVIDIA RTX 3000–5000 (x86_64, CUDA cu128, bakes large-v3) and Jetson Orin (arm64, bakes small) |
Evidence
Console and request contract.
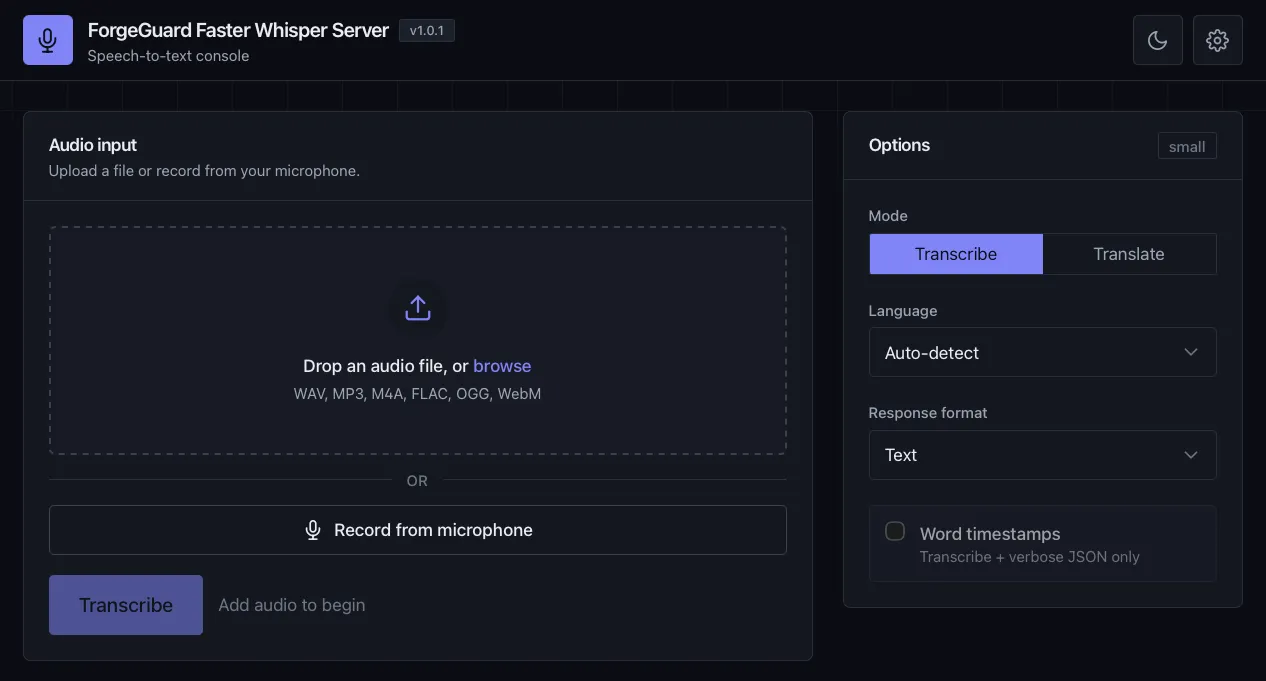
Transcribe audio with curl
curl -X POST http://localhost:8000/v1/audio/transcriptions \
  -F 'file=@audio.mp3' \
  -F 'response_format=text'
/health returns 200 immediately (status "warming" then "healthy"); /ready returns 200 once the model can transcribe.
Architecture
Data flow.
Clients speak the OpenAI API to a FastAPI interface layer that handles auth, upload limits, and the bounded work queue; inference runs on local GPU compute through CTranslate2 with telemetry surfaced alongside.
Deployment
Deployment paths.
Docker (x86_64 CUDA)
docker run -d --name whisper --gpus all -p 8000:8000 \
  ghcr.io/forgeguard-ai/faster-whisper-server:latest
RTX 3000–5000 series; pin a release tag such as :1.1.0 for stable deployments.
Docker (Jetson Orin)
docker run -d --name whisper --runtime nvidia -p 8000:8000 \
  ghcr.io/forgeguard-ai/faster-whisper-server-jetson:latest
arm64 image for JetPack 6 devices; bakes the small model for 8 GB Orin memory.
Docker Compose
docker compose -f deploy/docker-compose.local.yml up -dSingle-GPU local stack with HTTPS on 8443; Portainer variants in deploy/.
Kubernetes (Helm)
helm install whisper oci://ghcr.io/forgeguard-ai/charts/faster-whisper-server --version 1.1.0Probes wire the health contract in: startup/readiness on /ready, liveness on /health; GPU scheduling via nvidia.com/gpu limits; API keys from a Kubernetes Secret.
Compatibility
Support matrix.
| Target | Status | Notes |
|---|---|---|
| NVIDIA RTX 3000–5000 series (x86_64) | Supported | CUDA cu128 image bakes large-v3; ghcr.io/forgeguard-ai/faster-whisper-server |
| NVIDIA Jetson Orin (arm64) | Supported | JetPack 6 image bakes small (int8_float16); larger models only with confirmed memory headroom |
| CPU-only hosts | Supported (reduced performance) | DEVICE=cpu auto-downgrades compute type to int8 |
| AMD (ROCm), Intel | Planned | Tracked on the roadmap; no images published yet |
Responsibility
Privacy and data handling.
- Transcripts are sensitive PII: LOG_INPUT_TEXT defaults off and PERSIST_AUDIO defaults off, so neither transcript text nor uploaded audio is retained by default.
- Optional bearer authentication via API_KEY; upload size is bounded by MAX_UPLOAD_BYTES (25 MB default).
- The repository publishes data-handling guidance in docs/responsible-use.md and its security posture in docs/security.md.
Lineage & attribution
Where this work comes from.
An independent ForgeGuard AI server, originally derived from SYSTRAN/faster-whisper. Licensed MIT with required attributions in NOTICE.
- SYSTRAN/faster-whisperMIT
The inference library this server builds on.
- OpenAI WhisperMIT
Model weights, as converted to CTranslate2 format by Systran.
- CTranslate2MIT
The inference engine.
Status & limitations
Known limitations and roadmap.
- CTranslate2 cannot run float16 on CPU; the server auto-downgrades to int8 on CPU-only hosts.
- The 8 GB Jetson Orin shares memory between CPU and GPU; the Jetson image defaults to the small model and larger models need confirmed headroom.
- Models not baked into the image download from Hugging Face on first activation and need a cache volume to persist.
- AMD (ROCm) and Intel images are planned but not yet published.
Roadmap
- Real-time streaming transcriptionIncremental partial transcripts over persistent connections (WebSocket/SSE) with barge-in-friendly cancellation, alongside the existing request/response endpoints.
- More inference backendsAMD (ROCm) and Intel images as hardware becomes available to validate on.
Full history in the changelog; planned work is tracked in the repository roadmap.
Documentation
Read the docs.
Versioned documentation for Faster Whisper Server is published from the repository'sdocs/site/ tree.